Even if the test is run by an independent third party, they can always test open weight models against "finetuning attacks" or similar language which every model will fail for structural reasons.
Their financial future is on the line. The Chinese frontier labs have caught up before the IPO that would have allowed them to cash out.
All three demands in the paper make perfect sense from this perspective. Without chip export restrictions, the rest of the world will leapfrog them in a few months. This will happen regardless, since they have more competition than in-house talent, but a ban would buy more time. Testing and banning capable open-weight models would hinder public research into the technology, another speed bump to slow down the competition. Same thing for "distillation", we can't have large scale public evaluations of their products...
Add to that the restrictions on even in-house talent being allowed to work on the latest models, we might actually have a brain drain from Anthropic soon which would be a welcoming sign.
It's in Anthropic's best interest to focus the conversation on "distillation".
Imo the more interesting thing to focus on is that there are now several more labs with the expertise and capabilities to train trillion parameter models. That's a serious technical accomplishment and the main reason why open models are catching up to Anthropic and OpenAI (and local models are typically distillations of much larger models).
Who cares that they got some small amount of training data out of Claude. The crux is that the big US labs are not special, they just have a first mover advantage that's slowly shrinking as incremental progress becomes harder.
> The actual opposing argument is that it's impossible to create a billion dollar enterprise without a group effort
The other thing that we're often ignoring is that it's impossible to create a billion dollar enterprise without luck. You have to be at the right place at the right time.
For the most part only capital gets to roll the dice, but even before that it's a sign of the times that we take it seriously at all when people talk about "earning" a billion dollars. We could all do with a bit more humility.
I agree with most of what the author is saying, but the slogan that "a sufficiently detailed spec is code" can be misunderstood as "a sufficiently detailed spec is a program". The statement is only true if you read "code" as "statement in a formal language". Here's a (sketch of a) specification for a compiler:
> For every specification satisfied by the input program, the output program satisfies the same specification.
This is not a program and it does not become a program once you fill in the holes. Making the statement precise clearly requires a formal language, but that language can work at a higher level of abstraction than a programming language. So yes, a specification can absolutely be simpler than a program that implements it.
But that is not a specification for a compiler. That is just one of the requirement. It’s still missing all the error cases that can happen. Granted, most of those decisions will be taken at implementation time or during design discussions, but I believe if we noted them down, it would have been longer than the code. It’s just that people don’t bother and refer to the code for these kind of information.
> if we noted them down, it would have been longer than the code
If you are only noting down requirements of what the program is doing rather than how it should do that thing, I would expect that writing the requirements would necessarily be more succinct than writing the program.
It terrifies me every time I realize people are just jumping into writing code without specifying what that code is required to do. A day of hacking saves an hour of critical thought and planning.
What's your point? Sometimes things need to be retried. Sometimes there are small subtle details that make or break an idea. So what's the point of acting dismissively? If an old idea that didn't work now works, then what's the problem? Besides, progress is typically iterative, not through leaps and bounds. The vast majority of things that look like leaps are just because we don't see the steps between.
The reason I'm saying this is because that sentiment is often used to pass over working solutions and slows down their progress. So even if unintentional it should cause us to rethink how we respond. Otherwise we end up with such silly claims like "Einstein just used Tensors" and "Nash just used topology". In some sense these are accurate, but they are too high level descriptions (and these are real dismissals. Which again, so what? If it works, it works?).
Why is "novelty" even a question? Novelty is only ever in the eyes of the beholder.
> What is novel about the approach in the blog post? Serious question, I really can't tell after reading the post.
Honestly, I do not know, but I'll give you my best read on it.
1) Scale: Don't underestimate the importance of this. While I don't think scale is all you need, it certainly is a critical factor.
2) Different optimization: I may be missing something, but it looks like they are using a different optimizer. They mention that they're using the muon optimizer constraining to a Stiefel manifold. Neither of those things are unique on their own, but is their combination? This is where I'm uncertain because such a thing would be easy to miss. Maybe someone did and was unsuccessful with it. Maybe someone did, but was not at scale. Maybe someone did, it worked, and just nobody noticed (that happens a lot!).
So I think this is quite similar to how 99% of progress and breakthroughs are made: putting together ideas that seem unrelated and inventing some glue to generalize the process. At a high level this always looks like you're just putting existing things together, but that glue is really hard to make. And to continue that analogy, if we do a good enough job gluing things together then to anyone but an expert it'll look like there is no glue. It can be surprisingly difficult to tell if something is glued, welded, mated, milled, printed, or whatever. It usually takes a very keen eye to determine the answer non-destructively.
Apologies if this came across the wrong way. I really do want to know what the novel contributions of the post are, because the author implies that something about what they're doing is solving previously open problems:
> I figured out how to solve manifold Muon in the square case late last year, but I was unable to solve the full rectangular case and thus posed the problem as an open problem on the Modula docs. Jianlin Su solved the problem this summer
It sounds like the generalisation of projected gradient decent to "Muon" is what they're focusing on, but the derivation is all about the retraction map on the Stiefel manifold? I think I'm missing some background here.
I was uncertain but your other statements made me think that sentiment was unintentional. I just want to push back against it because it is too common and misused even with good intentions. I hope you don't see this as me saying anything about your character. Honestly, impressions are that you do care.
> It sounds like the generalisation of projected gradient decent to "Muon"
I'm not a niche expert here, but do have knowledge in adjacent/overlapping domains. It sounds like you're in a similar boat? I ask because this pulls back to what I was trying to say about sometimes needing an expert eye.
If it helps, here's the "paper" for the Muon optimizer[0] and here's a follow-up[1]. Muon is definitely a gradient decent technique, but so are Adam, SGD, Ada, and many more[2].
The big thing of Muon is using NewtonSchulz5. So you update parameters with θ_{t-1} - η[NS_5(μB_{t-1} + ∇L(θ_{t-1}))] (I bracketed so you can see that this is just a specific version of θ_{t-1} - ηF(∇L(θ_{t-1}),...) which the standard gradient descent -- θ - η∇L(θ) -- is in that class of functions, right?). So we should be careful to over generalize and say that this is just gradient descent. You could even say [1] is "just [0] but with weight-decay" (or go look at the Adam and AdamW algos ;)
But one thing I should add is that gradient descent algorithms aren't topologically aware. I was able to find this post which asks a related question, trying to find what the conditions are for a surface's geodesic to align with gradient descent (note Newton differs from GD too). I don't think this paper is creating a solution where the GD formulation results in following a geodesic to the minimum, but my take is that it is working towards that direction. And to clarify, we'd want to follow the geodesic because that gives us the shortest or most energy efficient path (which ever perspective you want to use). In optimization we want to try to accomplish these two things (and more!): 1) take the "best" path to the optima, 2) find the best optima. Unfortunately these are ill-defined and there's not always objective answers to them. But in an ideal gradient descent algorithm we'd want it to go to the global minimum and take the fastest path, right? So with that it helps to be aware of the geometry (part of why people look at the Hessian but that comes at the cost of increased computation even if the additional information can get us there in fewer steps. So that's not (always) "the best").
I know this isn't a full answer and maybe with more reading I'll have a better one for you. But I'm hoping my answer can at least help you see some of the underlying nuanced problems that (_I think_) the authors are trying to get at. Hopefully I'm not too far off base lol. I'm hoping someone with more expertise can jump in and provide corrections/clarifications in the mean time.
The reason deep learning is alchemy is that none of these deep theories have predictive ability.
Essentially all practical models are discovered by trial and error and then "explained" after the fact. In many papers you read a few paragraphs of derivation followed by a simpler formulation that "works better in practice". E.g., diffusion models: here's how to invert the forward diffusion process, but actually we don't use this, because gradient descent on the inverse log likelihood works better. For bonus points the paper might come up with an impressive name for the simple thing.
In most other fields you would not get away with this. Your reviewers would point this out and you'd have to reformulate the paper as an experience report, perhaps with a section about "preliminary progress towards theoretical understanding". If your theory doesn't match what you do in practice - and indeed many random approaches will kind of work (!) - then it's not a good theory.
It's true that there is no directly predictive model of deep learning, and it's also true that there is some trial and error, but it is wrong to say that therefore there is no operating theory at all. I recommend reading Ilyas 30 papers (here's my review of that set:
https://open.substack.com/pub/theahura/p/ilyas-30-papers-to-...) to see how shared intuitions and common threads are clearly developed over the last decade+
The usual way to check whether a definition is correct is to prove properties about it that you think should hold. TLA+ has good support for this, both with model checking as well as simple proofs.
> even if this doesn’t lead to AGI, at the very least it’s likely the final “warning shot” we’ll get before it’s suddenly and irreversibly here.
I agree that it's good science fiction, but this is still taking it too seriously. All of these "projections" are generalizing from fictional evidence - to borrow a term that's popular in communities that push these ideas.
Long before we had deep learning there were people like Nick Bostrom who were pushing this intelligence explosion narrative. The arguments back then went something like this: "Machines will be able to simulate brains at higher and higher fidelity. Someday we will have a machine simulate a cat, then the village idiot, but then the difference between the village idiot and Einstein is much less than the difference between a cat and the village idiot. Therefore accelerating growth[...]" The fictional part here is the whole brain simulation part, or, for that matter, any sort of biological analogue. This isn't how LLMs work.
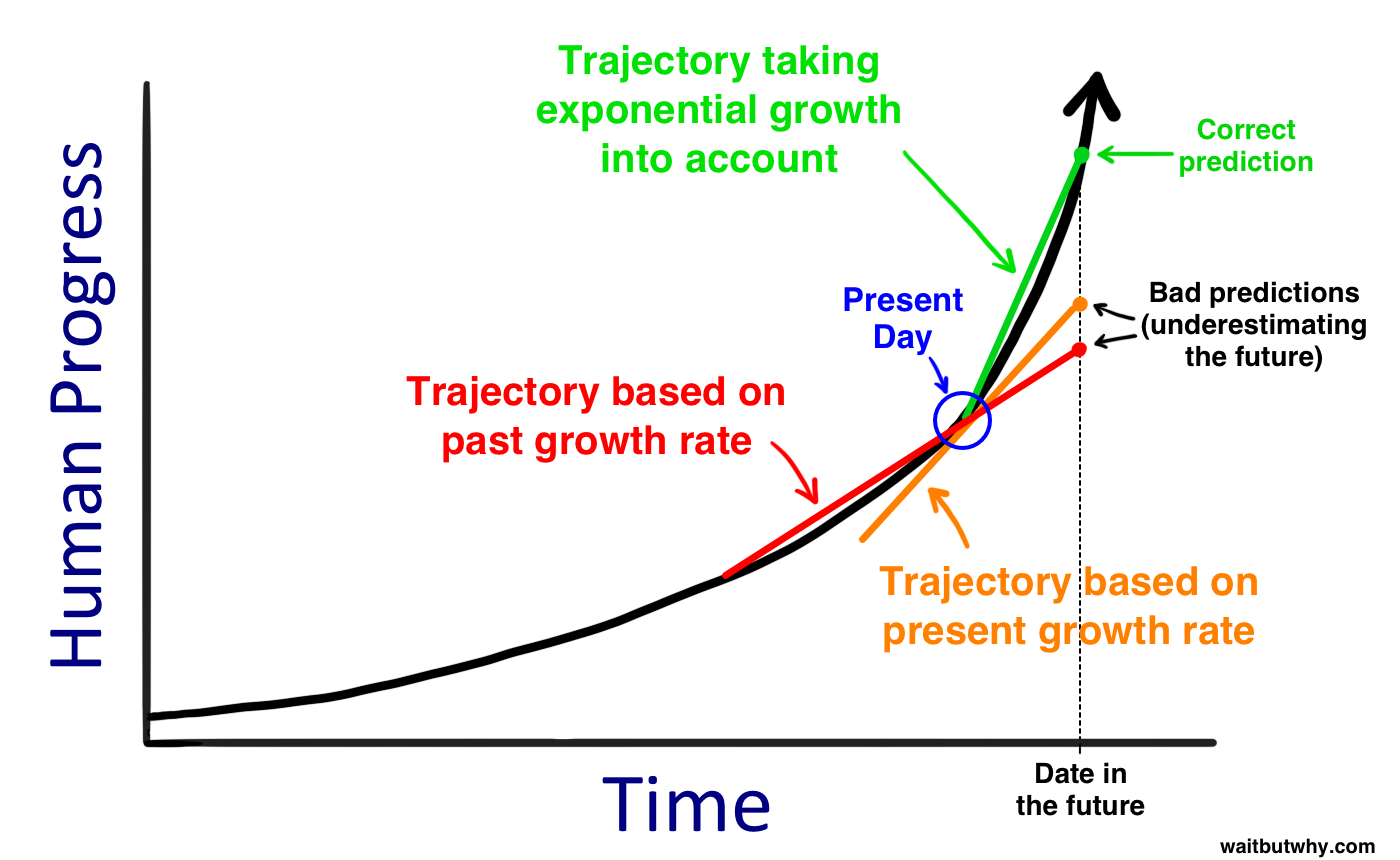
We never got a machine as smart as a cat. We got multi-paragraph autocomplete as "smart" as the average person on the internet. Now, after some more years of work, we have multi-paragraph autocomplete that's as "smart" as a smart person on the internet. This is an imperfect analogy, but the point is that there is no indication that this process is self-improving. In fact, it's the opposite. All the scaling laws we have show that progress slows down as you add more resources. There is no evidence or argument for exponential growth. Whenever a new technology is first put into production (and receives massive investments) there is an initial period of rapid gains. That's not surprising. There are always low-hanging fruit.
We got some new, genuinely useful tools over the last few years, but this narrative that AGI is just around the corner needs to die. It is science fiction and leads people to make bad decisions based on fictional evidence. I'm personally frustrated whenever this comes up, because there are exciting applications which will end up underfunded after the current AI bubble bursts...
If you gather up a couple million of the smartest people on earth along with a few trillion dollars, and you add in super ambitious people eager to be culturally deified, you significantly increase the chance for breakthroughs. It's all probabiliities, though. But, right now there's no better game to bet on.
>There is no evidence or argument for exponential growth
I think the growth you are thinking of, self improving AI, needs the AI to be as smart as a human developer/researcher to get going and we haven't got there yet. But we quite likely will at some point.
and the article specifically mentions the fictional company (clearly designed to generalize the Google/OpenAI's of the world) are supposedly (according to the article) working on building that capability. First by augmenting human researchers, later by augmenting itself.
> Someday we will have a machine simulate a cat, then the village idiot... This isn't how LLMs work.
I think you misunderstood that argument. The simulate the brain thing isn't a "start from the beginning" argument, it's an "answer a common objection" argument.
Back around 2000, when Nick Bostrom was talking about this sort of thing, computers were simply nowhere near powerful enough to come even close to being smart enough to outsmart a human, except in very constrained cases like chess; we did't even have the first clue how to create a computer program to be even remotely dangerous to us.
Bostrom's point was that, "We don't need to know the computer program; even if we just simulate something we know works -- a biological brain -- we can reach superintelligence in a few decades." The idea was never that people would actually simulate a cat. The idea is, if we don't think of anything more efficient, we'll at least be able to simulate a cat, and then an idiot, and then Einstein, and then something smarter. And since we almost certainly will think of something more efficient than "simulate a human brain", we should expect superintelligence to come much sooner.
> There is no evidence or argument for exponential growth.
Moore's law is exponential, which is where the "simulate a brain" predictions have come from.
> It is science fiction and leads people to make bad decisions based on fictional evidence.
The only "fictional evidence" you've actually specified so far is the fact that there's no biological analog; and that (it seems to me) is from a misunderstanding of a point someone else was making 20 years ago, not something these particular authors are making.
I think the case for AI caution looks like this:
A. It is possible to create a superintelligent AI
B. Progress towards a superintelligent AI will be exponential
C. It is possible that a superintelligent AI will want to do something we wouldn't want it to do; e.g., destroy the whole human race
D. Such an AI would be likely to succeed.
Your skepticism seems to rest on the fundamental belief that either A or B is false: that superintelligence is not physically possible, or at least that progress towards it will be logarithmic rather than exponential.
Well, maybe that's true and maybe it's not; but how do you know? What justifies your belief that A and/or B are false so strongly, that you're willing to risk it? And not only willing to risk it, but try to stop people who are trying to think about what we'd do if they are true?
What evidence would cause you to re-evaluate that belief, and consider exponential progress towards superintelligence possible?
And, even if you think A or B are unlikely, doesn't it make sense to just consider the possibility that they're true, and think about how we'd know and what we could do in response, to prevent C or D?
> Moore's law is exponential, which is where the "simulate a brain" predictions have come from.
To address only one thing out of your comment, Moore's law is not a law, it is a trend. It just gets called a law because it is fun. We know that there are physical limits to Moore's law. This gets into somewhat shaky territory, but it seems that current approaches to compute can't reach the density of compute power present in a human brain (or other creatures' brains). Moore's law won't get chips to be able to simulate a human brain, with the same amount of space and energy as a human brain. A new approach will be needed to go beyond simply packing more transistors onto a chip - this is analogous to my view that current AI technology is insufficient to do what human brains do, even when taken to their limit (which is significantly beyond where they're currently at).
> The idea is, if we don't think of anything more efficient, we'll at least be able to simulate a cat, and then an idiot, and then Einstein, and then something smarter. And since we almost certainly will think of something more efficient than "simulate a human brain", we should expect superintelligence to come much sooner.
The problem with this argument is that it's assuming that we're on a linear track to more and more intelligent machines. What we have with LLMs isn't this kind of general intelligence.
We have multi-paragraph autocomplete that's matching existing texts more and more closely. The resulting models are great priors for any kind of language processing and have simple reasoning capabilities in so far as those are present in the source texts. Using RLHF to make the resulting models useful for specific tasks is a real achievement, but doesn't change how the training works or what the original training objective was.
So let's say we continue along this trajectory and we finally have a model that can faithfully reproduce and identify every word sequence in its training data and its training data includes every word ever written up to that point. Where do we go from here?
Do you want to argue that it's possible that there is a clever way to create AGI that has nothing to do with the way current models work and that we should be wary of this possibility? That's a much weaker argument than the one in the article. The article extrapolates from current capabilities - while ignoring where those capabilities come from.
> And, even if you think A or B are unlikely, doesn't it make sense to just consider the possibility that they're true, and think about how we'd know and what we could do in response, to prevent C or D?
It might make sense to consider, but it doesn't make sense to invest non-trivial resources.
This isn't the part that bothers me at all. I know people who got grants from, e.g., Miri to work on research in logic. If anything, this is a great way to fund some academic research that isn't getting much attention otherwise.
The real issue is that people are raising ridiculous amounts of money by claiming that the current advances in AI will lead to some science fiction future. When this future does not materialize it will negatively affect funding for all work in the field.
And that's a problem, because there is great work going on right now and not all of it is going to be immediately useful.
I think the idea with LLMs leading to AGI is more like:
Natural language is a fuzzy context aware state machine of some sorts that can theoretically represent any arbitrarily complex state in the outside world given enough high quality text.
And by reiterating and extrapolating the rules found in human communication an AI could by the sheer ability to simulate infinitely long discussions discover new things, given the ability to independently verify outcomes.
> So let's say we continue along this trajectory and we finally have a model that can faithfully reproduce and identify every word sequence in its training data and its training data includes every word ever written up to that point. Where do we go from here?
This is a fundamental misunderstanding of the entire point of predictive models (and also of how LLMs are trained and tested).
For one thing, ability to faithfully reproduce texts is not the primary scoring metric being used for the bulk of LLM training and hasn't been for years.
But more importantly, you don't make a weather model so that it can inform you of last Tuesday's weather given information from last Monday, you use it to tell you tomorrow's weather given information from today. The totality of today's temperatures, winds, moistures, and shapes of broader climatic patterns, particulates, albedos, etc etc etc have never happened before, and yet the model tells us something true about the never-before-seen consequences of these never-before-seen conditions, because it has learned the ability to reason new conclusions from new data.
Are today's "AI" models a glorified autocomplete? Yeah, but that's what all intelligence is. The next word I type is the result of an autoregressive process occurring in my brain that produces that next choice based on the totality of previous choices and experiences, just like the Q-learners that will kick your butt in Starcraft choose the best next click based on their history of previous clicks in the game combined with things they see on the screen, and will have pretty good guesses about which clicks are the best ones even if you're playing as Zerg and they only ever trained against Terran.
A highly accurate autocomplete that is able to predict the behavior and words of a genius, when presented with never before seen evidence, will be able to make novel conclusions in exactly the same way as the human genius themselves would when shown the same new data. Autocomplete IS intelligence.
New ideas don't happen because intelligences draw them out of the aether, they happen because intelligences produce new outputs in response to stimuli, and those stimuli can be self-inputs, that's what "thinking" is.
If you still think that all today's AI hubbub is just vacuous hype around an overblown autocomplete, try going to Chatgpt right now. Click the "deep research" button, and ask it "what is the average height of the buildings in [your home neighborhood]"?, or "how many calories are in [a recipe that you just invented]", or some other inane question that nobody would have ever cared to write about ever before but is hypothetically answerable from information on the internet, and see if what you get is "just a reproduced word sequence from the training data".
> We have multi-paragraph autocomplete that's matching existing texts more and more closely.
OK, I think I see where you're coming from. It sounds like what you're saying is:
E. LLMs only do multi-paragraph autocomplete; they are and always will be incapable of actual thinking.
F. Any approach capable of achieving AGI will be completely different in structure. Who knows if or when this alternate approach will even be developed; and if it is developed, we'll be starting from scratch, so we'll have plenty of time to worry about progress then.
With E, again, it may or may not be true. It's worth noting that this is a theoretical argument, not an empirical one; but I think it's a reasonable assumption to start with.
However, there are actually theoretical reasons to think that E may be false. The best way to predict the weather is to have an internal model which approximates weather systems; the best way to predict the outcome of a physics problem is to have an internal model which approximates the physics of the thing you're trying to predict. And the best way to predict what a human would write next is to have a model of a human mind -- including a model of what the human mind has in its model (e.g., the state of the world).
There is some empirical data to support this argument, albeit in a very simplified manner: They trained a simple LLM to predict valid moves for Othello, and then probed it and discovered an internal Othello board being simulated inside the neural network:
And my own experience with LLMs better match the "LLMs have an internal model of the world" theory than the "LLMs are simply spewing out statistical garbage" theory.
So, with regard to E: Again, sure, LLMs may turn out to be a dead end. But I'd personally give the idea that LLMs are a complete dead end a less than 50% probability; and I don't think giving it an overwhelmingly high probability (like 1 in a million of being false) is really reasonable, given the theoretical arguments and empirical evidence against it.
With regard to F, again, I don't think this is true. We've learned so much about optimizing and distilling neural nets, optimizing training, and so on -- not to mention all the compute power we've built up. Even if LLMs are a dead end, whenever we do find an architecture capable of achieving AGI, I think a huge amount of the work we've put into optimizing LLMs will put is way ahead in optimizing this other system.
> ...that the current advances in AI will lead to some science fiction future.
I mean, if you'd told me 5 years ago that I'd be able to ask a computer, "Please use this Golang API framework package to implement CRUD operations for this particular resource my system has", and that the resulting code would 1) compile out of the box, 2) exhibit an understanding of that resource and how it relates to other resources in the system based on having seen the code implementing those resources 3) make educated guesses (sometimes right, sometimes wrong, but always reasonable) about details I hadn't specified, I don't think I would have believed you.
Even if LLM progress is logarithmic, we're already living in a science fiction future.
EDIT: The scenario actually has very good technical "asides"; if you want to see their view of how a (potentially dangerous) personality emerges from "multi-paragraph auto-complete", look at the drop-down labelled "Alignment over time", and specifically what follows "Here’s a detailed description of how alignment progresses over time in our scenario:".
>All of these "projections" are generalizing from fictional evidence - to borrow a term that's popular in communities that push these ideas.
This just isn't correct. Daniel and others on the team are experienced world class forecasters. Daniel wrote another version of this in 2021 predicting the AI world in 2026 and was astonishingly accurate. This deserves credence.
>he arguments back then went something like this: "Machines will be able to simulate brains at higher and higher fidelity.
Complete misunderstanding of the underlying ideas. Just in not even wrong territory.
>We got some new, genuinely useful tools over the last few years, but this narrative that AGI is just around the corner needs to die. It is science fiction and leads people to make bad decisions based on fictional evidence.
You are likely dangerously wrong. The AI field is near universal in predicting AGI timelines under 50 years. With many under 10. This is an extremely difficult problem to deal with and ignoring it because you think it's equivalent to overpopulation on mars is incredibly foolish.
I respect the forecasting abilities of the people involved, but I have seen that report described as "astonishingly accurate" a few times and I'm not sure that's true. The narrative format lends itself somewhat to generous interpretation and it's directionally correct in a way that is reasonably impressive from 2021 (e.g. the diplomacy prediction, the prediction that compute costs could be dramatically reduced, some things gesturing towards reasoning/chain of thought) but many of the concrete predictions don't seem correct to me at all, and in general I'm not sure it captured the spiky nature of LLM competence.
I'm also struck by the extent to which the first series from 2021-2026 feels like a linear extrapolation while the second one feels like an exponential one, and I don't see an obvious justification for this.
>2025:...Making models bigger is not what’s cool anymore. They are trillions of parameters big already. What’s cool is making them run longer, in bureaucracies of various designs, before giving their answers.
I mean MoE/agent work was being done in 2021 I'm pretty sure. Definitely more accurate than most predictions but perhaps not revolutionary to state that the tail follows the dog.
I'm personally very excited about the progress in interactive theorem proving. Before the current crop of deep learning heuristics there was no generally useful higher-order automated theorem proving system. Automated theorem proving could prove individual statements based on existing lemmas, but that only works in extremely restricted settings (propositional or first-order logic). The problem is that in order to apply a statement of the form "for all functions with this list of properties, ..." you need to come up with a function that's related to what you're trying to prove. This is equivalent to coming up with new lemmas and definitions, which is the actually challenging part of doing mathematics or verification.
There has finally been progress here, which is why you see high-profile publications from, e.g., Deepmind about solving IMO problems in Lean. This is exciting, because if you're working in a system like Coq or Lean your progress is monotone. Everything you prove actually follows from the definitions you put in. This is in stark contrast to, e.g., using LLMs for programming, where you end up with a tower of bugs and half-working code if you don't constantly supervise the output.
---
But well, the degree of excitement is my own bias. From other people I spoke to recently:
- Risk-assessment diagnostics in medicine. There are a bunch of tests that are expensive and complex to run and need a specialist to evaluate. Deep learning is increasingly used to make it possible to do risk assessments with cheaper automated tests for a large population and have specialists focus on actual high-risk cases. Progress is slow for various reasons, but it has a lot of potential.
- Weather forecasting uses a sparse set of inputs: atmospheric data from planes, weather baloons, measurements at ground stations, etc. This data is then aggregated with relatively stupid models to get the initial conditions to run a weather simulation. Deep learning is improving this part, but while there has been some encouraging initial progress this needs to be better integrated with existing simulations (purely deep learning based approaches are apparently a lot worse at predicting extreme weather events). Those simulations are expensive, they're running on some of the largest supercomputers in the world, which is why progress is slow.
And a self driving car is not even necessary if we’re thinking about solving transportation problems. Train and bus are better at solving road transportation at scale.
Adding to this, inference is getting cheaper and more efficient all the time. The investment bubble is probably the biggest reason why inference hardware is so expensive at the moment and why startups in this sector are only targeting large scale applications.
Once this bubble bursts, local inference will become even more affordable than it already is. There is no way that there will be a moat around running models as a service.
---
Similarly, there probably won't be a "data moat". The whole point of large foundation models is that they are great priors. You need relatively few examples to fine tune an LLM or diffusion model to get it to do what you want. So long as someone releases up to date foundation models there is no moat here either.
Agreed, this is a big step forward. Geometry problems are in a different class, since you can translate them into systems of polynomial equations and use well known computer algebra algorithms to solve them.
By contrast, this kind of open ended formalization is something where progress used to be extremely slow and incremental. I worked in an adjacent field 5 years ago and I cannot stress enough that these results are simply out of reach for traditional automated reasoning techniques.
Real automatic theorem proving is also useful for a lot more than pure mathematics. For example, it's simple to write out an axiomatic semantics for a small programming language in lean and pose a question of the form "show that there exists a program which satisfies this specification".
If this approach scales it'll be far more important than any other ML application that has come out in the last few years.
> Agreed, this is a big step forward. Geometry problems are in a different class, since you can translate them into systems of polynomial equations and use well known computer algebra algorithms to solve them.
The blog post indicates the opposite. The geometry problem in the IMO problem set was solved by AlphaGeometry 2, which is an LLM based on Google's Gemini. LLMs are considered relatively general systems. But the other three solved problems were proved by AlphaProof, which is a narrow RL system that is literally based on AlphaZero, the Go and Chess AI. Only its initial (bootstrapping) human training data (proofs) were formalized and augmented by an LLM (Gemini).
Only slightly more general. It only works for games that are zero-sum, deterministic, have no hidden information, and discrete game state and moves. Other examples include connect-4.
So finding Lean proofs can be conceptualized as a zero-sum game?
Another basic requirement is that valid moves / inference steps and the winning condition can be efficiently verified using some non-AI algorithm. Otherwise there would not be a reward signal for the reinforcement learning algorithm. This is different from answering most natural language questions, where the answer can't be checked trivially.
Theorem proving can be formulated as a game, see e.g., https://plato.stanford.edu/entries/logic-games/ and interactive theorem provers can verify that a proof is correct (and related sub problems, such as that a lemma application is valid).
Conceptually, if you're trying to show a conjunction, then it's the other player's turn and they ask you for a proof of a particular case. If you're trying to show a disjunction then it's your turn and you're picking a case. "Forall" is a potentially infinite conjunction, "exists" is a potentially infinite disjunction.
In classical logic this collapses somewhat, but the point is that this is still a search problem of the same kind. If you want to feel this for yourself, try out some proofs in lean or coq. :)
I don't think AlphaZero is related to this work, apart from both being NN-based. AlphaZero and its training pipeline fundamentally only works for "chess-like" two-player games, where the agent can play against itself and slowly improve through MCTS.
"AlphaProof is a system that trains itself to prove mathematical statements in the formal language Lean. It couples a pre-trained language model with the AlphaZero reinforcement learning algorithm, which previously taught itself how to master the games of chess, shogi and Go."


Their financial future is on the line. The Chinese frontier labs have caught up before the IPO that would have allowed them to cash out.
All three demands in the paper make perfect sense from this perspective. Without chip export restrictions, the rest of the world will leapfrog them in a few months. This will happen regardless, since they have more competition than in-house talent, but a ban would buy more time. Testing and banning capable open-weight models would hinder public research into the technology, another speed bump to slow down the competition. Same thing for "distillation", we can't have large scale public evaluations of their products...